
LLM Knowledge Base: Do Solo Operators Actually Need One?
An LLM knowledge base sounds powerful — but is building one the right move for solo operators? Here's an honest breakdown of the trade-offs.
An LLM knowledge base can make a scattered archive searchable, but it also creates a second system that must be governed. For a solo operator, the right question is not “Can I build one?” It is “Will retrieval save more time than ingestion, review, and cleanup consume?”
Information checked October 13, 2026.
What an LLM knowledge base actually does
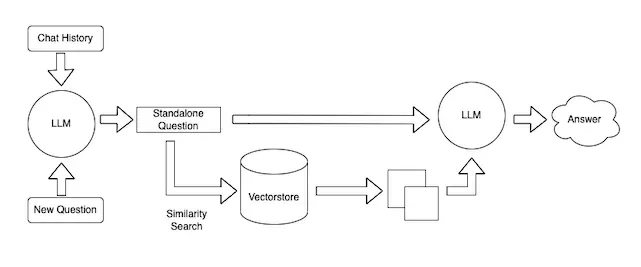
The useful core is retrieval: documents are indexed, relevant passages are selected for a question, and a model answers from those passages. OpenAI describes the same basic pattern in its retrieval and file-search documentation. A generated wiki adds summaries and links, but those are model outputs—not automatically verified facts.
That distinction matters. A knowledge base can improve recall across proposals, interviews, policies, and research notes. It cannot guarantee that a source is current, that an extracted claim is correct, or that the answer includes every exception. The related LLM wiki concept is best treated as a navigable view over sources, not a replacement for them.
When a solo operator gets real value
A knowledge base is a good candidate when the same source set is reused, search is already painful, and wrong answers can be checked against citations. Examples include comparing recurring client requirements, finding decisions across project notes, or locating evidence in a stable research archive.
It is a weak fit when the material changes daily, the corpus is small enough to search manually, or the goal is simply to finish one deliverable. In those cases, a temporary project folder or an AI workspace with connected sources may remove more friction than a permanent indexing pipeline.
The costs that demos hide
Ingestion quality. Scanned PDFs, tables, duplicated exports, and missing metadata produce weak retrieval before the model writes a word.
Freshness. A useful system needs a rule for replacement, deletion, and conflict resolution. “Latest” is not meaningful unless dates and source authority are stored.
Access control. Client files should not become visible to unrelated projects. Permissions need to apply during indexing and retrieval, not only in the interface.
Evaluation. Test questions should cover exact lookup, synthesis, conflicting sources, missing evidence, and refusal. A fluent answer without a supporting passage is a failure.
Maintenance. Every connector and transformation can fail. Someone still owns failed imports, stale copies, and sensitive data retention.
Build, buy, or skip: a practical decision
Build a custom system only when you need unusual source handling, strict deployment control, or retrieval behavior that packaged tools cannot provide. Use a managed workspace when standard file and app connections cover the job and you would rather evaluate outputs than operate infrastructure. Skip the permanent knowledge base when the task is temporary or the sources are too volatile.
Before choosing, run a small corpus through five real questions. Require source links, record misses, and compare the time saved with the time spent preparing material. If the pilot cannot reliably point back to the right evidence, adding more documents will usually magnify the problem.
Original visual references
These images are restored from the article's original publication to preserve interface, workflow, and comparison context. Any product UI, pricing, benchmark result, or model availability shown is a historical capture; verify current official information before making a decision.
A minimum governance checklist
- Name the source owner and update cadence.
- Keep original documents reachable from every generated answer.
- Separate authoritative records from commentary and drafts.
- Define what the system must do when evidence is absent or contradictory.
- Review access, deletion, and export behavior before adding client data.
- Re-run a fixed evaluation set after changing models, chunking, or connectors.
For most solo operators, the winning version is smaller than the imagined one: one high-value corpus, clear citations, and a review habit. The objective is not to manufacture a second brain. It is to shorten the path from a question to inspectable evidence.
Related posts
The Markdown Resume — Maintain One Source, Export Every Format
Keep your resume as one Markdown source and export print-ready PDF, Word, and web on demand — structure, git history, and what ATS parsing…
Markdown for Note-Taking — A Workflow That Outlives Any App
A markdown note-taking workflow built on plain files: naming, structure, links, and AI review. Why plain text outlives any app, and how to…
What Is an Obsidian Vault? Files, Settings, and Boundaries
An Obsidian vault is a local folder containing Markdown notes, attachments, and vault-specific settings. Learn what lives inside it, what…
https://floatboat.ai/blog/llm-knowledge-base-solo-operators