OpenAI GPT-6 Cyber: Who Gets Access and What It Can Do
OpenAI’s GPT-6 Cyber starts with a limited Daybreak Red rollout. Check eligibility, Codex and API access, and token pricing, then see how…
Kostja11 min read
22 articles in this category.
OpenAI’s GPT-6 Cyber starts with a limited Daybreak Red rollout. Check eligibility, Codex and API access, and token pricing, then see how…
GPT-6.1 Sol brings near-Astra coding, computer use, and professional-work performance at one-fifth of Astra's token prices. Here is what…
Jev is TypeSafe AI's System One model: typed probabilistic decisions instead of generated text, claimed 193.6x faster and 444.6x cheaper.…
DeepSeek V4.1 Flash is now the production Flash model. Verify its model ID, 1M context, vision support, peak pricing, retired aliases, and…
GPT-6 Astra explained with current official facts: $10/$50 pricing, 1.05M context, tools, long-context premiums, Critical cyber safeguards,…
What Gemini 3.8 Flash changes after 3.7: model specs, thinking levels, pricing, tool behavior, token trade-offs, limitations, and a…
MiniMax H3 Max Live explained as an experimental continuous-video pipeline, with official status, pricing, throughput, buffering,…
DeepSeek Harness is DeepSeek's own AI coding agent — the layer that turns V4 into an agent. Architecture, v0.1 open-source release, and…
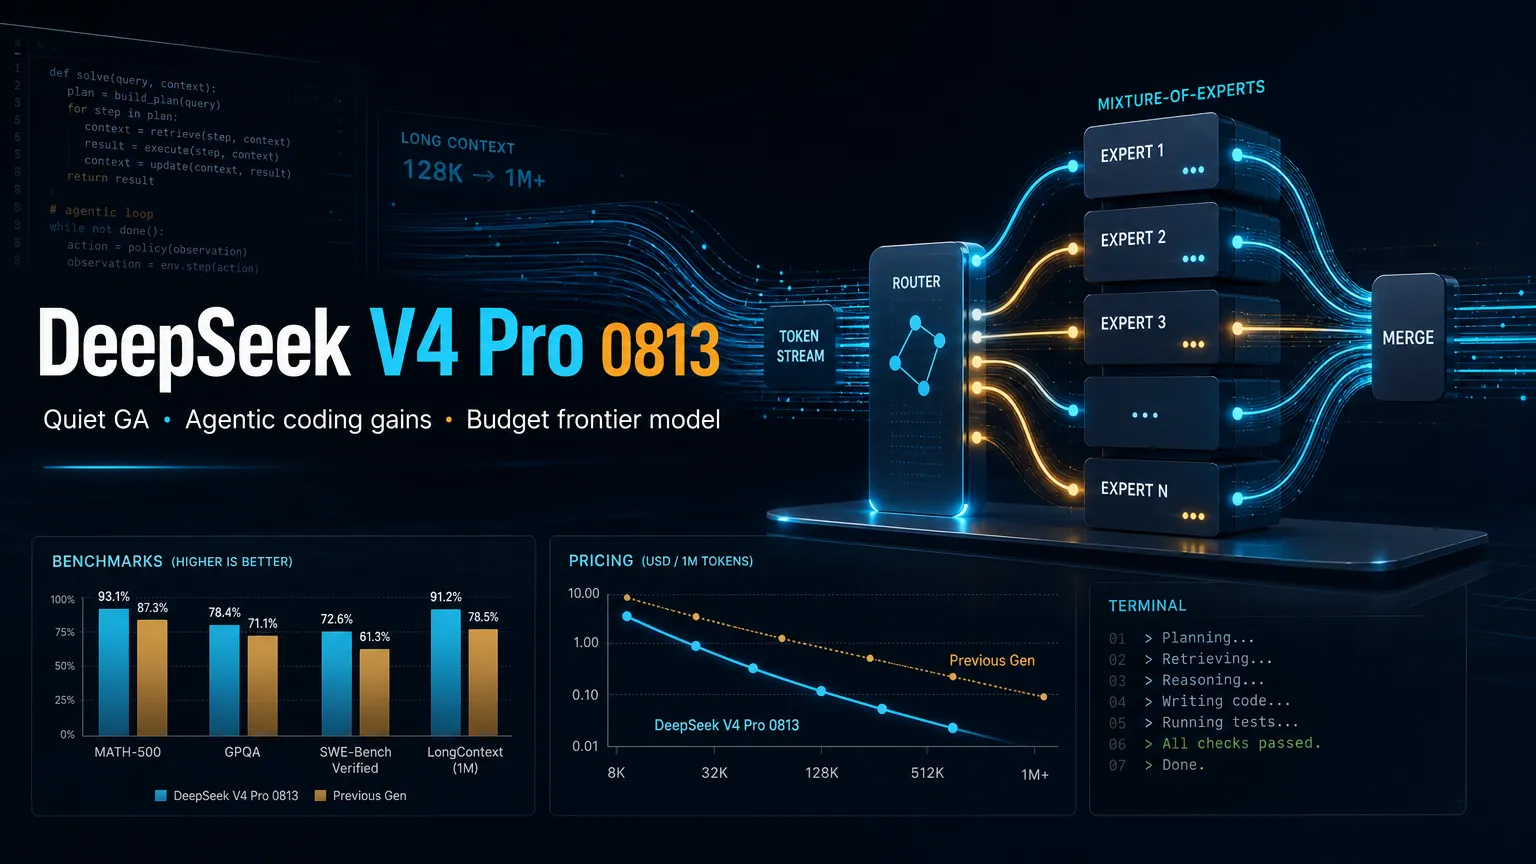
DeepSeek V4 Pro 0813 went GA with no announcement. Specs, claimed agent benchmarks, the pricing window before the hike, and how it stacks…
How to verify GLM-5.3 weight availability, license terms, and self-hosting requirements before comparing them with the hosted API and…
A sourced guide to Grok 4.6: 500K context, reasoning modes, API pricing, independent benchmarks, long-context costs, and whether it still…
MiniMax H3 is an open-weight omni-modal video model that turns text, images, clips, and audio into 2K video with native stereo sound.…
Kimi K3 explained through its open-weight boundary, Kimi K3 License, kimi-k3 API ID, 1M context, current pricing, tool compatibility, and…
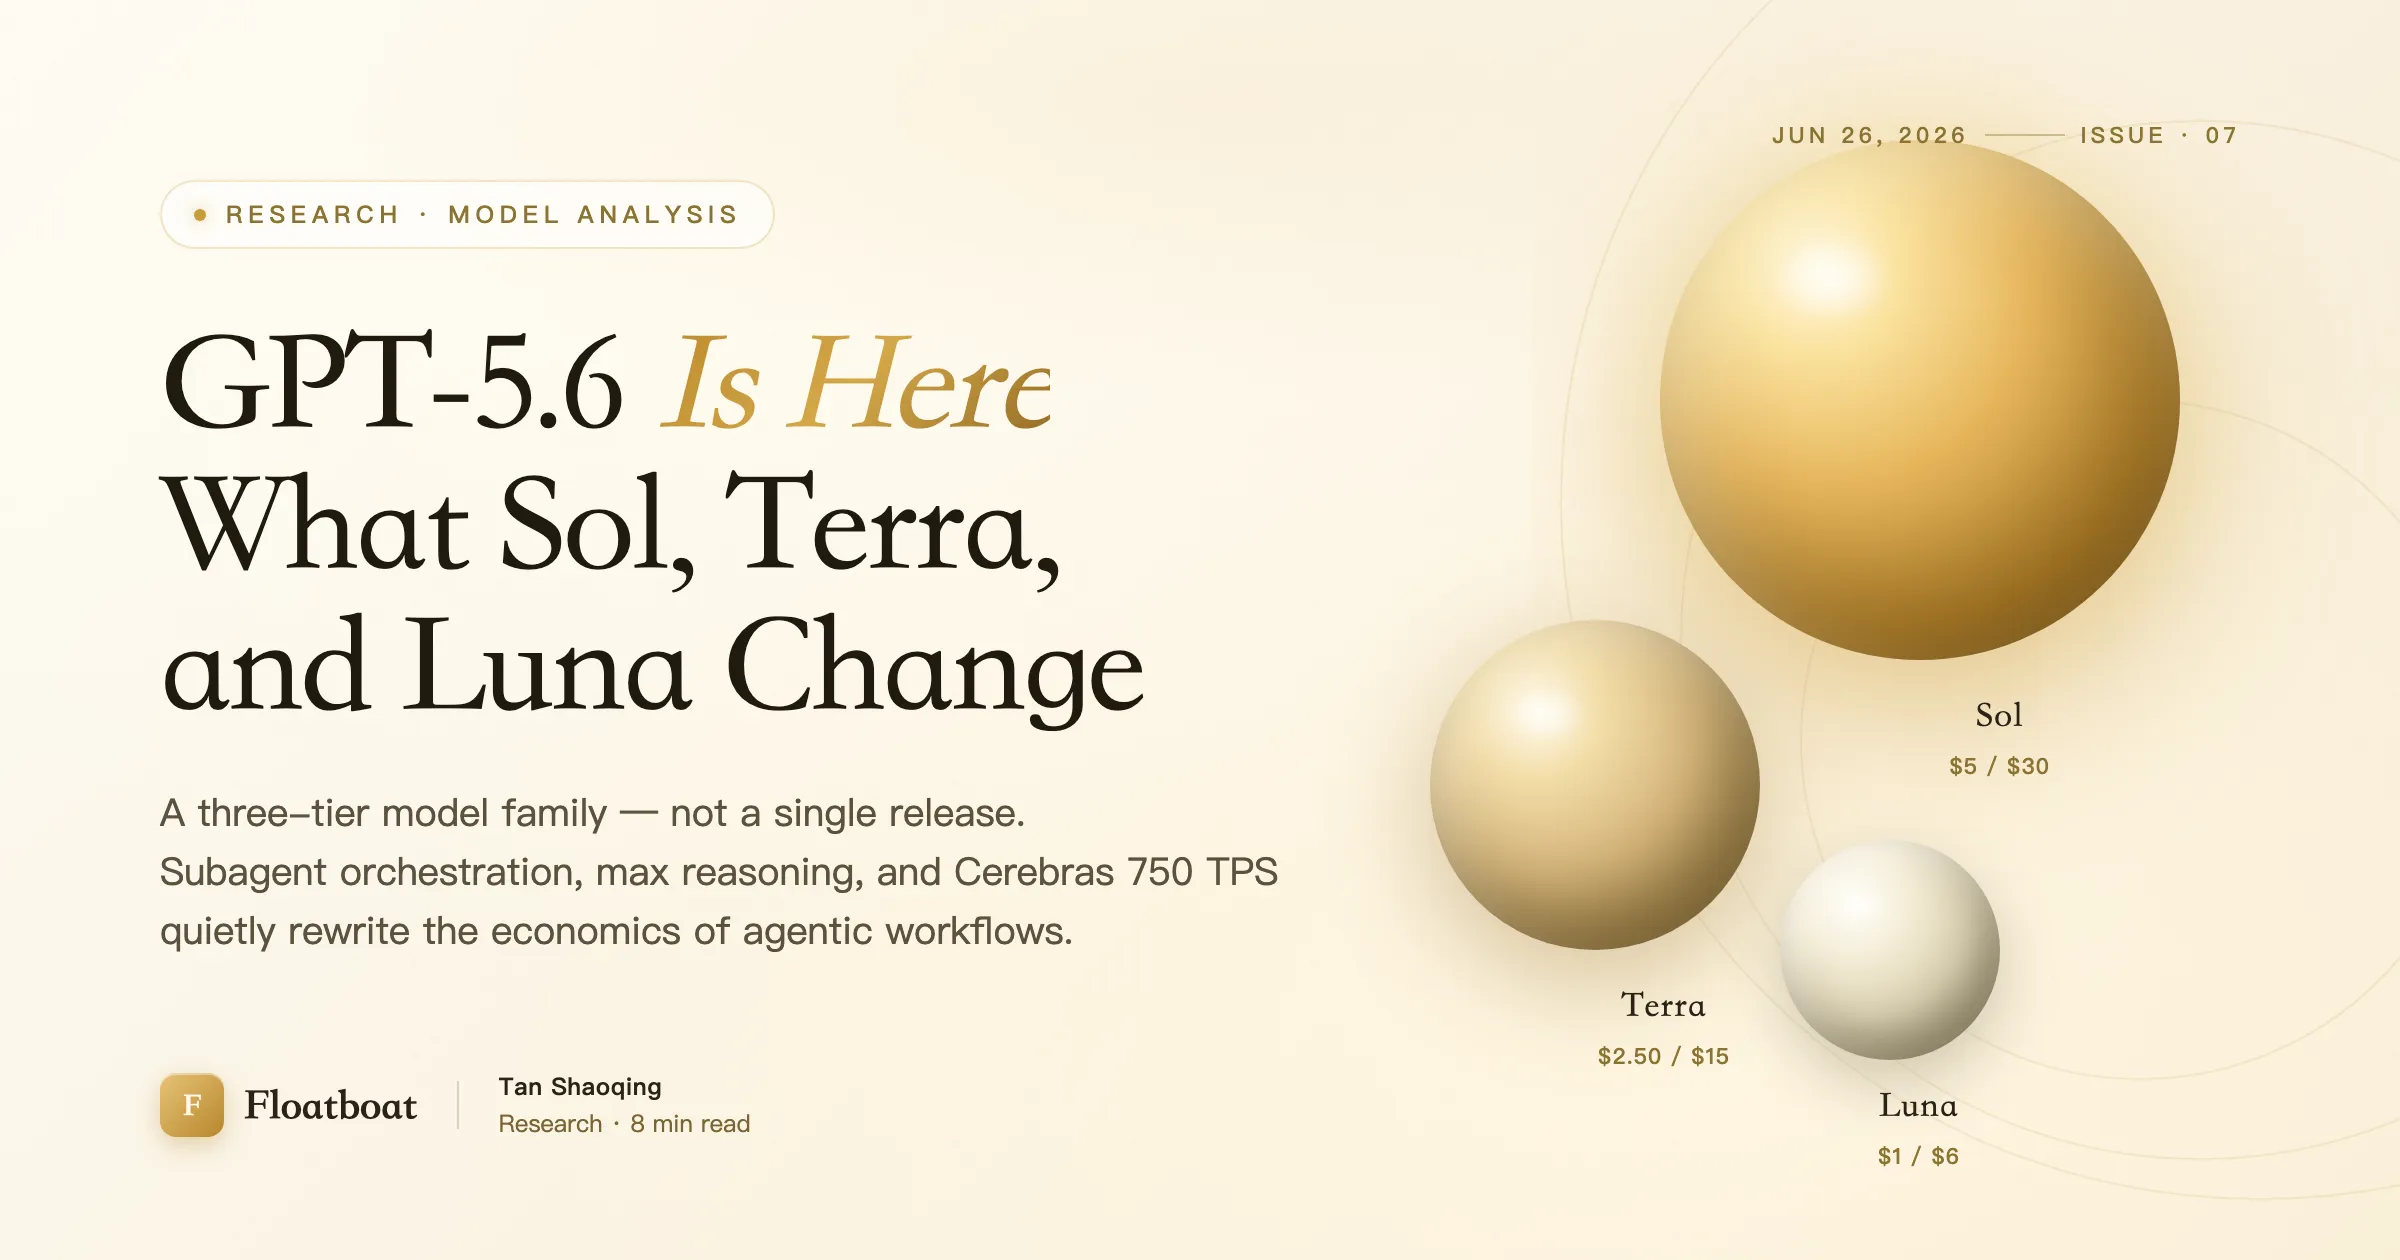
Compare GPT-5.6 Sol, Terra, and Luna using current API prices, context limits, reasoning modes, tool support, and a workload-based model…
A practical framework for choosing AI reasoning effort and response speed by task risk, latency, cost, and review burden.
Gemini 3.5 Flash is stable but no longer Google's newest Flash model. Compare its capabilities, cost, privacy terms, and workflow fit…
What Meta Muse Spark offers solo operators, what changed by version 1.3, and how to test whether switching models improves a real workflow.
A controlled GPT Image 2 manga workflow for character sheets, panel generation, lettering, continuity review, rights checks, and…
Can GPT Image 2 produce a usable film or short-video storyboard on its own? Here's what a one-person creator can and can't pull off.
A practical guide to using GPT-6 Astra in a one-person company: task fit, costs, controls, evaluation, Floatboat access, and when a cheaper…
The Grok 3 API is retired and its model slug redirects to Grok 4.3. Learn what existing users are billed, which xAI model fits each…
A current DeepSeek V4 API guide for solo operators: model IDs, peak and off-peak prices, cache economics, routing caveats, and a practical…
/blog/category/model-benchmarks